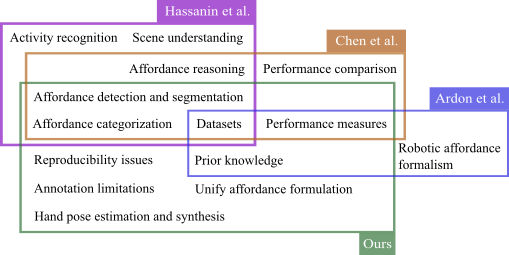
Contrary to previous surveys, we compare image-based datasets for visual affordance prediction,
highlighting their similarities and limitations. We consider elements such as: the environment type (e.g. indoor),
the camera viewpoint (e.g. third person); object categories (e.g. containers), type of images (e.g. mixed-reality),
occlusions (e.g. hand manipulating the object), and annotation (e.g. accuracy and procedure).
Each dataset is specific to an affordance redefinition rather than the unified formulation, preventing datasets reuse.
Furthermore, annotating affordances in images and videos is non-trivial due to ambiguous regional boundaries, overlapping action zones, and the complexity of labelling 3D end-effector poses.
These challenges limit the cross-datasets evaluation of methods and the scalability of datasets, as manual annotations are time-consuming and ambiguous, and require expensive resources
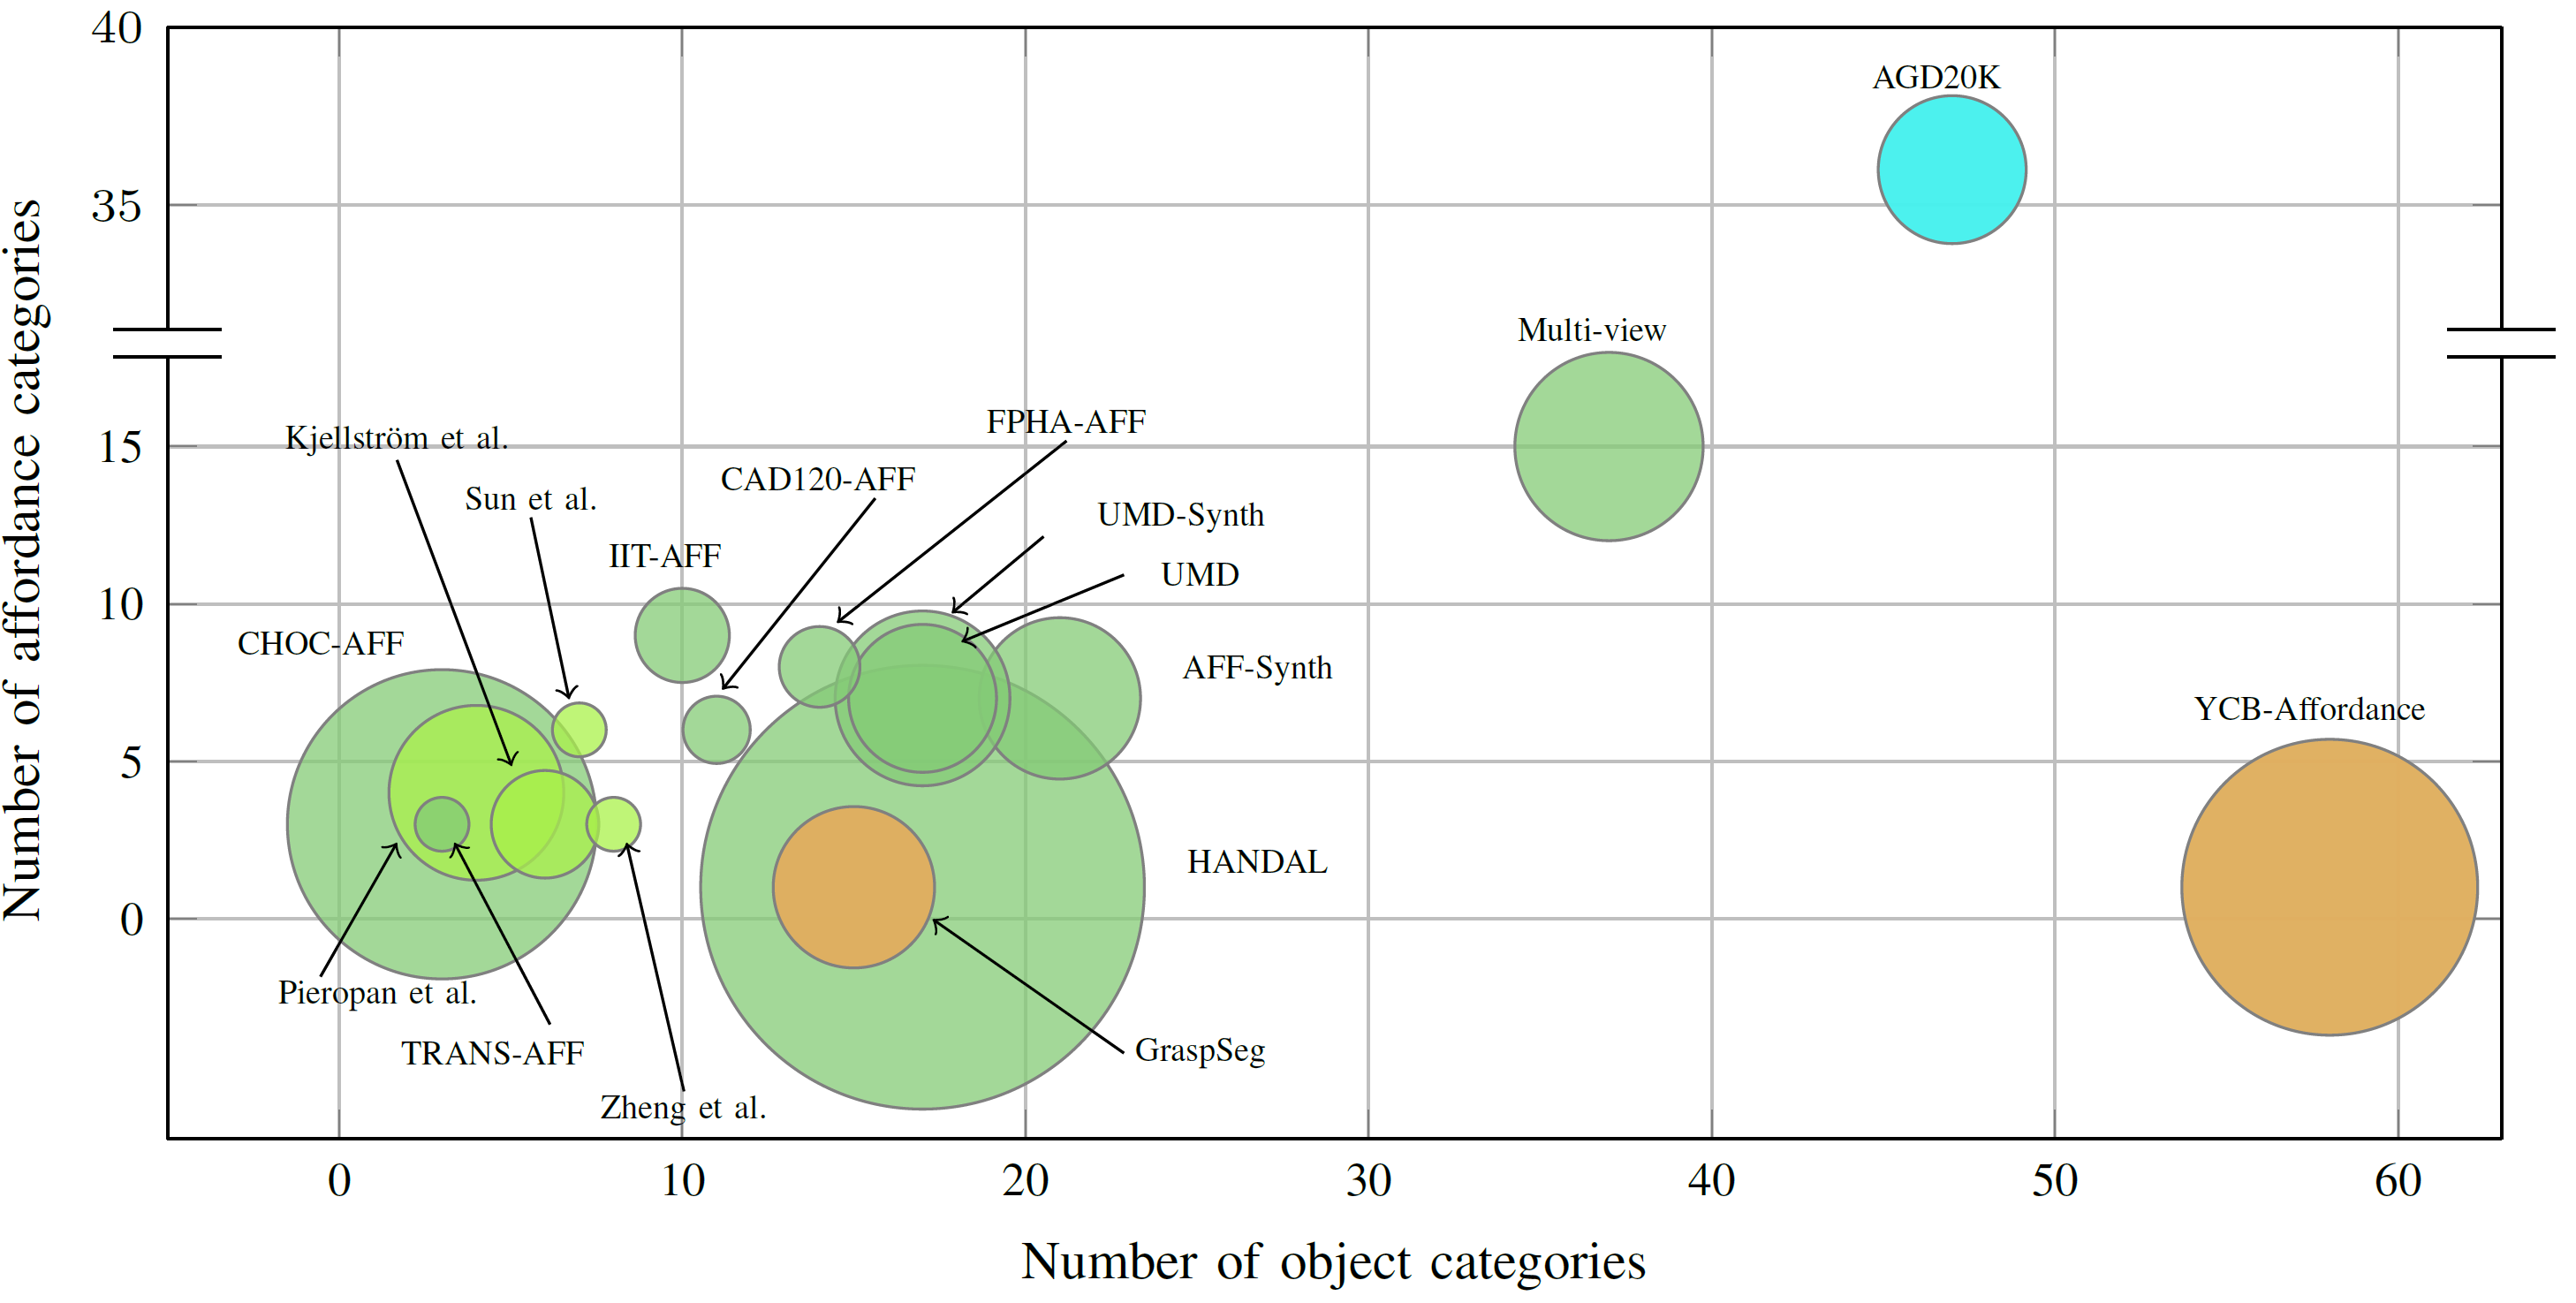
The majority of the analysed datasets has fewer than 20 object categories and 10 affordances, focusing on tools and containers.